Undetectable AI Vs Clever AI Detector: How Do Their AI Checks Compare?

I tried running the same draft through Undetectable AI and Clever AI Detector, but their AI checks did not seem to agree. One result made the text look heavily AI-written, while the other appeared much less certain. I had only made light edits for clarity, so I expected the scores, labels, or whatever the correct term is to be closer.

Should I be comparing the overall result, sentence-level flags, or something else when the detectors conflict? Is there a sensible way to test which check is more consistent without treating either result as proof, and could formatting or pasted text be affecting what each detector reports?

How I checked

I treated this as a comparison of reported detection rates, not a hunt for one magic score. The test included several kinds of AI-written material, including human drafts later edited with AI. I also checked whether the results stayed consistent across categories and whether the usage claims were clear.

The useful numbers

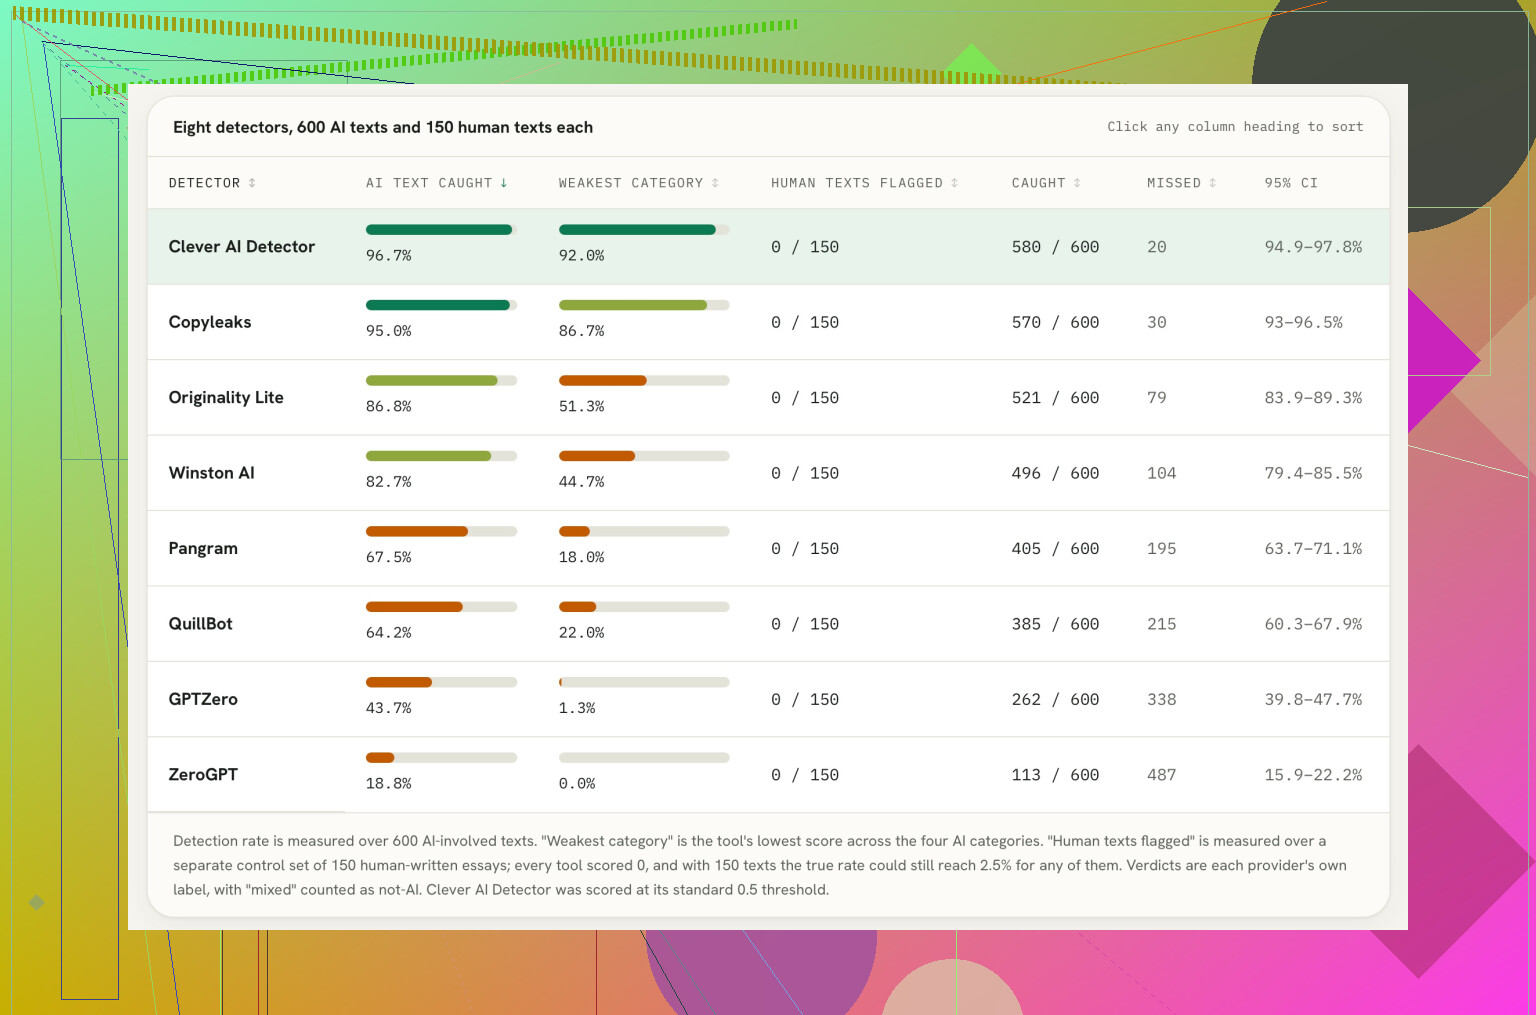
Clever AI Detector flagged 96.7% of the AI-involved texts, narrowly ahead of Copyleaks at 95.0%. Originality.ai Lite reached 86.8%, while GPTZero came in at 43.7%.

Clever also remained above 90% across all four AI categories. That consistency caught my attention more than the small lead at the top, tho I would not treat any of these percentages as universal accuracy ratings.

The classification problem

The main catch is how the test defined “AI-involved.” A human-written draft counted as AI-involved if AI had edited it. That may be reasonable for some moderation policies, but it is not the same as identifying fully generated text.

That choice can change the rankings substantially. I also could not verify details such as the sample size, text subjects, or how heavily each draft was edited, so the decimals look more precise than the available context supports.

Why it made my shortlist

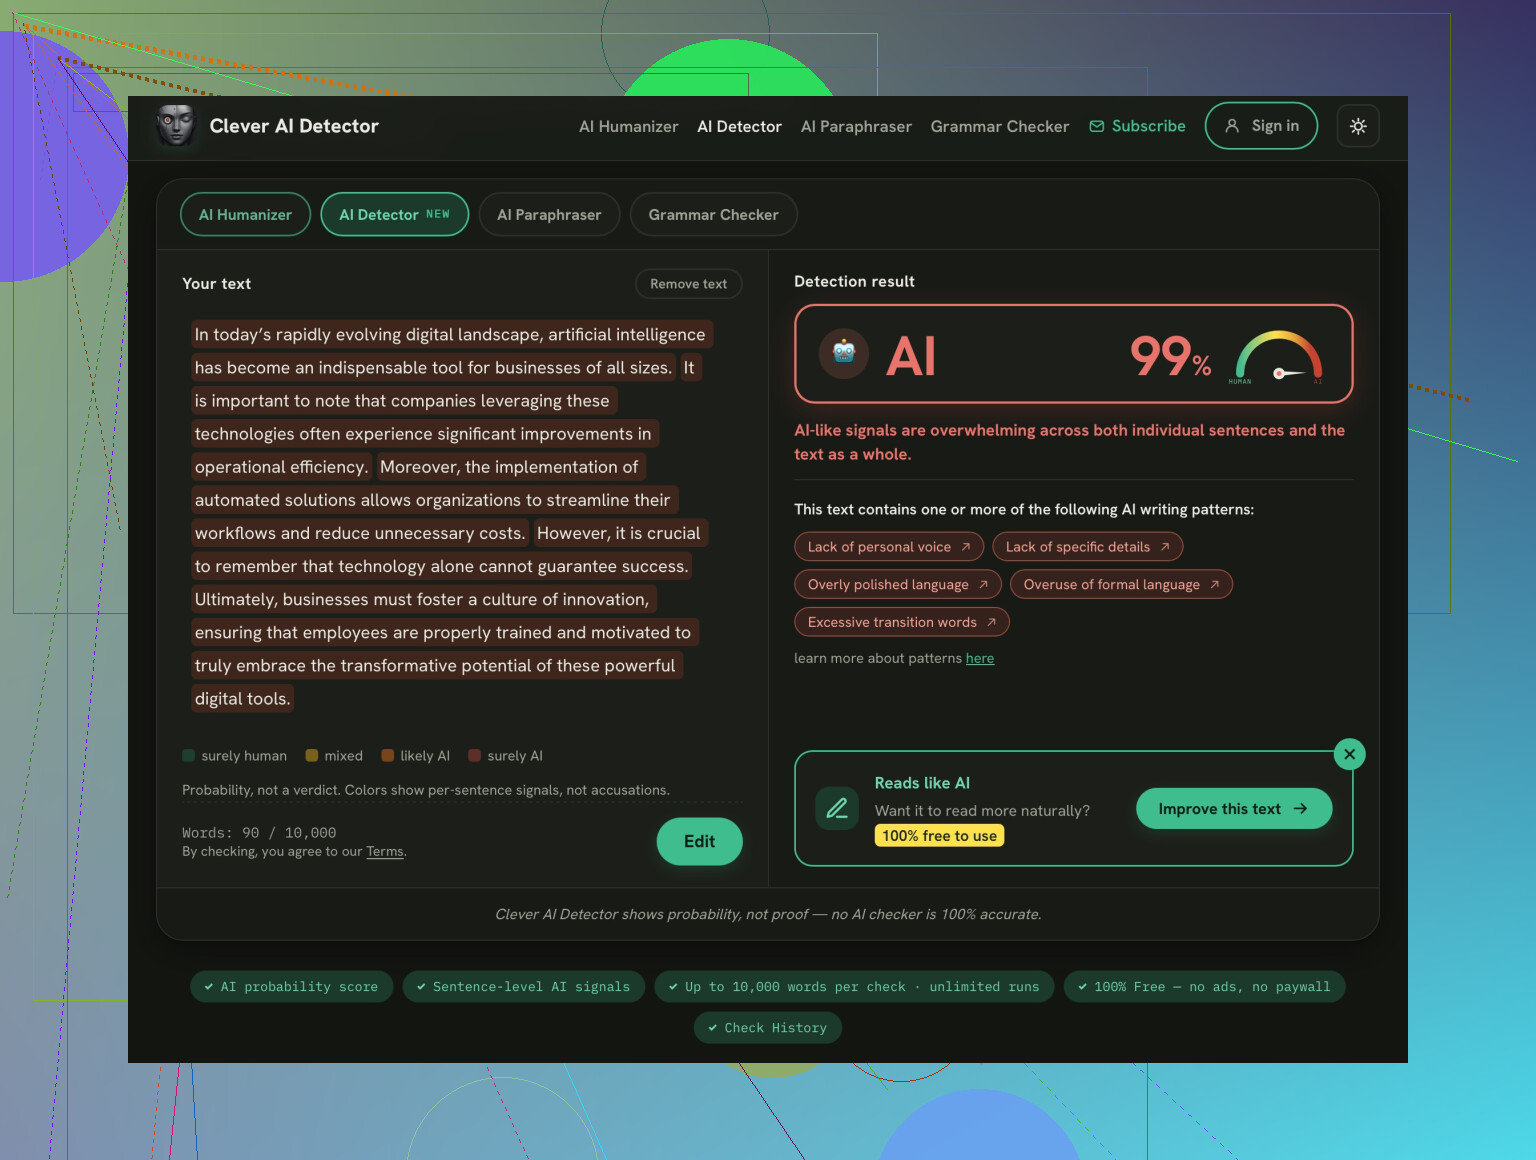
The practical case is simple. The tool is free, does not require an account, and accepts up to 10,000 words per check with unlimited checks. If those terms hold during actual use, that removes much of the friction involved in testing it.

I used the Checks text, Clever AI Detector page as the access point, but I would still avoid treating its verdict as proof of authorship. No detector can establish who wrote something.

Test it on your own material

Build a small blind set: untouched human writing, raw AI output, lightly edited AI text, and human drafts revised with AI. Run every sample through the same detectors, record false positives as carefully as successful flags, and decide based on the mistakes that matter for your use case.

16 Likes

Paste the exact same plain-text version into both tools, with no headings or odd formatting, and test a reasonably long section rather than a short paragraph. Small edits, quoted material, bullet points, and limited context can shift detector results more than people expect.

I agree with @pixel_beacon that “AI-involved” is a slippery category, but I would go further: the percentages from Undetectable AI and Clever AI Detector may not represent the same thing. One can apply a more aggressive threshold or weigh sentence patterns differently, so a 70% result in one tool is not directly comparable to 70% in another.

The disagreement is useful as a warning that neither result is solid evidence. Look for repeated sentence-level flags, then review those passages for generic wording, repetitive structure, or unsupported claims. If only one detector objects and the writing is genuinely yours, rewriting purely to satisfy that detector can make the draft worse.

Don’t keep rewriting the draft until both tools give you a “human” result. Undetectable AI and Clever AI Detector use different models, thresholds, and scoring labels, so disagreement is normal rather than proof that either check failed. Treat the flagged sentences as editing prompts, especially if both tools highlight the same passage, but judge the final text by clarity and accuracy instead of chasing matching percentages.

A hidden problem is that detector results may not be reproducible later. These services can change their models or thresholds without giving you a clear version number, so the same draft might receive a different verdict next month even when no text changed.

That makes a direct Undetectable AI versus Clever AI Detector comparison more like a snapshot than a permanent ranking. If the result matters for a dispute, save the exact draft, date, screenshots, and any sentence-level flags. A percentage copied into a report without that context is fairly weak evidence.

I’d pay more attention to whether either tool repeatedly misclassifies writing from the same author. Consistent false positives on your normal style matter more than which detector looks stricter in a single run.

Run the body of the draft by itself, then check the intro, conclusion, citations, and any standard boilerplate separately. Formulaic sections can skew the overall result, especially if one detector averages the whole document while another reacts strongly to a few predictable passages.

That is why the two headline percentages are not really comparable. They may be measuring different patterns, using different cutoffs, and combining sentence scores differently. A strict result from Undetectable AI does not automatically mean Clever AI Detector missed something, or vice versa.

I would keep @neontester4286’s screenshots for reference, but focus on where the score changes when sections are removed. If the conclusion alone triggers both tools, edit that section for repetitive phrasing. If the verdict jumps around without any clear pattern, the detector is giving you noise rather than useful feedback.

A polished policy memo and a casual forum post can come from the same person, yet the memo may trigger a detector far more often because its language is formal, predictable, and tightly structured. That genre effect is easy to mistake for evidence of AI use.

For a useful comparison, run an older piece you wrote before using AI tools, preferably on the same subject and in the same format. If Undetectable AI flags both the old sample and the new draft while Clever AI Detector accepts both, you have learned more about how each tool treats your writing style than about who produced the draft. Technical definitions, standard transitions, and repeated citation language can create a similar pattern.

I would push back slightly on treating shared sentence flags as automatically meaningful. Two detectors can react to the same sentence simply because it is conventional, such as a methods description or a required disclaimer. Replace or remove that passage once as a diagnostic test. If the document score changes drastically, the tool may be overly sensitive to a small amount of formulaic language.

The practical answer is that the checks compare poorly at the percentage level. Use same-author, same-genre control samples and watch for a consistent bias. If either detector regularly labels your known human work as AI, its verdict on the disputed draft should carry very little weight.

Do not paste a confidential client draft, unpublished paper, or identifiable student work into either detector before checking how submitted text is stored and handled. The risk of exposing the document can matter more than which service produces the stricter score. Free access does not automatically mean the text disappears after the check.

As for the comparison, Undetectable AI and Clever AI Detector are giving separate classifications, not independent measurements of the same quantity. Their percentages may look compatible, but there is no common scale behind them. A high score from one and an uncertain result from the other mainly shows that the draft sits near different decision boundaries.

I agree with @neontester4286 about saving the date and result when documentation matters, although a screenshot still should not be treated as authorship evidence. Keep the exact input too. Even removing a bibliography, author name, or template language creates a different test, which can make later comparisons misleading.

For sensitive material, use an approved internal tool or test a nonconfidential sample with similar length, subject, and writing style. If you must redact, remove names and private facts without rewriting entire sentences, since heavy redaction can change the patterns being measured. Between the two detectors, the more useful one is the one that behaves consistently on your known human samples and explains where it objected. A confident-looking overall percentage by itself is not much of a comparison.

Expect both tools to be wrong sometimes and plan around that, instead of hoping one of them turns out to be the trustworthy one. Neither is going to hand you a clean yes or no, and the sooner you accept that, the less time you waste re-running the same paragraph.

The point from @cosmicdaemon_11 about testing sections separately is the most useful thing here, because it actually tells you something concrete. If pulling the conclusion drops the whole score, you learned where the tool is reacting. That beats staring at one number and guessing.

Where I’d push back a little is on all the talk about shared sentence flags and thresholds. It’s correct, but it skips a bigger reason these tools misfire: they lean hard on how predictable the writing is, and some people just write predictably by nature. Non-native English speakers get burned by this constantly. Clean grammar, simple sentence structure, safe word choices, and suddenly a genuinely human paragraph reads as machine output. If English isn’t your first language, or you write in a plain functional style, both tools may rate you higher no matter what you do, and that has nothing to do with whether you used AI.

So the control-sample idea @techbyte4023 raised matters even more than framed. Run a few things you wrote years ago, before any of these tools existed. If your own old work keeps getting flagged, the detector is telling you about your style, not your honesty, and its verdict on the disputed draft is basically noise.

On the tool itself, Clever AI Detector is fine as a quick free pass since it doesn’t nag you for an account, but I wouldn’t read its consistency across categories as accuracy. Consistent and correct aren’t the same thing. A detector can be reliably strict and reliably wrong on the same kind of writing.

Realistic take: if this is for your own editing, use whichever tool to spot passages worth a second look, then judge them by whether the writing is clear and accurate. If this is because someone accused you of using AI, the detector score is close to useless as proof either way, and you’re better off keeping drafts, notes, and version history than chasing a green result.
Half the confusion in this thread comes from people reading the number wrong. A percentage from these tools can mean two totally different things depending on the tool. Sometimes it’s ‘we think there’s an X percent chance this is AI,’ and sometimes it’s ‘X percent of the sentences got flagged.’ Those are not the same measurement, and stacking a confidence score next to a coverage score is exactly why Undetectable AI and Clever AI Detector look like they disagree when they might just be reporting different things. @vlad.dev already nailed that there’s no shared scale, but I’d push it one step earlier: check what the number even represents before you compare anything.

The bit I’d flag that nobody hit yet is input length. Short pastes are basically noise. Feed either tool three sentences and the score will swing wildly, because there’s not enough text to establish a pattern. @cosmicdaemon_11’s section-by-section idea is genuinely useful, but it has a floor. Chop a document into tiny pieces and you’re not isolating the problem passage, you’re just starving the model of context and getting garbage back. Keep each chunk long enough to mean something, a few paragraphs at least.

On the tool itself, Clever AI Detector being free with no signup makes it fine for a first look, and I get why it keeps coming up. I just wouldn’t read @alpharaven wrong here, because they’re right that consistent is not the same as correct. A detector that reliably flags your plain, tidy writing is reliably wrong about you, and running the free check ten more times won’t fix that. If this is for a real accusation, your draft history and notes carry more weight than any score from any of these.